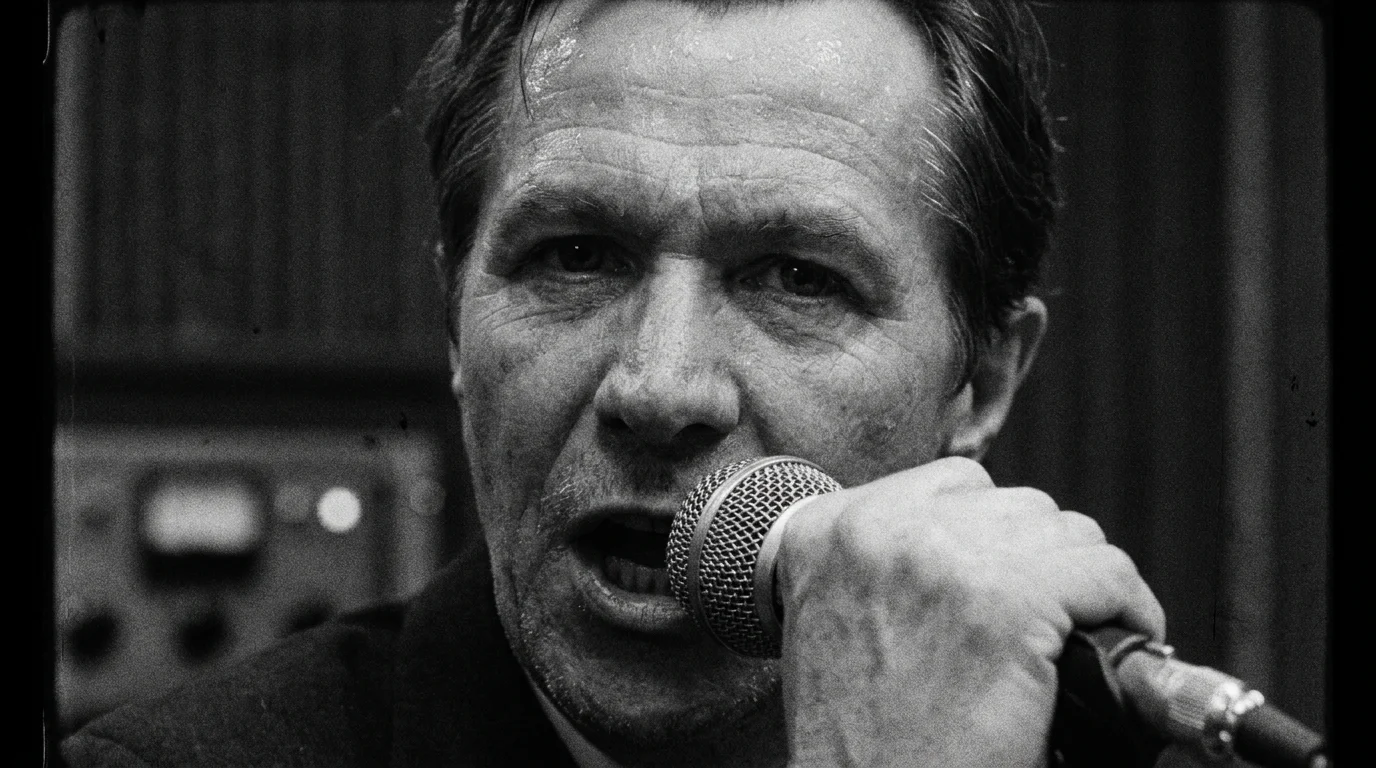
You can tell everything about a room by the silence a veteran actor leaves behind. In the hush between syllables, when the air conditioning hums faintly through the soundstage insulation and the boom mic hovers motionless, Gary Oldman crafts meaning. It is not just the dialect or the rasp carved out by decades of cigarettes and Shakespeare; it is the calculated pause. You lean forward from your couch because the silence stretches just long enough to make your pulse jump.
Then you watch the international cut streaming through a fiber-optic connection on a rainy Tuesday evening, and something feels fundamentally broken. The breath catches in the wrong pocket of the sentence. The tension dissipates before the punchline can land, clipped and accelerated as if an invisible hand yanked the scene forward by a quarter of a beat. The cadence feels counterfeit because, behind the closed doors of a post-production facility across the globe, it actually was.
Oldman recently discovered that automated post-production software had quietly cannibalized his dramatic rhythm. Without his sign-off, sound engineers working under frantic localization mandates ran algorithmic cadence resynchronization scripts across his primary dialogue track. What you witnessed was not an actor losing his grip on a dramatic scene, but a digital scalpel shaving milliseconds off human hesitation to fit automated localization templates.
The Phantom Metronome: When Code Collides with Craft
For generations, the actor’s contract carried an unwritten covenant: the face and voice captured on the day belong to the character. We understood that visual effects could polish away a stray wire or swap out a gloomy London sky, but the vocal performance remained sacred. Think of pacing as a delicate wire suspended between two buildings; if you shorten the wire while the performer is halfway across, they tumble into the void.
Streaming algorithms, however, run on throughput, bandwidth conservation, and mechanical symmetry. When a prestige series is localized across fifty territories in forty-eight hours, human pauses become liabilities. To automated dialogue processors, a three-second hesitation looks like dead space waiting to be optimized. Digital time-compression algorithms slice those microscopic gaps into ribbons, squeezing Oldman’s masterclass in subtext down to a hurried exchange that matches dubbed audio waveforms.
The studio executives didn’t view it as vandalism; they viewed it as procedural efficiency. By shaving eight frames from every significant silence, they eliminated synchronization drift between regional subtitles and dubbed foreign-language audio tracks. To an engineer managing thousands of audio streams, dead air is wasted memory. To you as a viewer, that missing beat erases the exact moment an unspoken secret shifts between two characters.
- The Weeknd masks live vocal slips under aggressive stadium sub-bass frequencies
- Henry Cavill exposes violent suspension rig drops compressing spine during action shoot
- Joaquin Phoenix confronts studio brass after biometric screen tests force sanitized reshoots
- Charlize Theron rejects digital skin smoothing demanding unforgiving raw macro framing
- Millie Bobby Brown stiff red carpet posture sparks viral split speculation
The Soundstage Confession: Inside the Midnight QC Suite
Consider the reality of Marcus Vance, a 44-year-old veteran re-recording mixer based in Burbank who spent two decades threading dialogue reels through traditional mixing consoles. On a late Thursday shift last winter, Vance was tasked with quality-checking an overseas auxiliary stem for a marquee period thriller. As he monitored the dialogue track through nearfield speakers, the waveforms did not match the handwritten production notes.
“I watched the cursor skim across a dialogue stem where Oldman played an interrogator,” Vance recalled during a recent industry guild panel. “His jaw was still tightening on screen, holding the room hostage before delivering a lethal line, but the audio track had already jumped into the consonants. A cloud-based plug-in had scanned the localized dub track and snapped the English production audio to match the tighter syllables of the foreign translation. It completely severed the actor’s nervous system from his spoken breath.”
The Anatomy of Spoken Interference: Where Performance Gets Clipped
To understand why this technological intrusion hits so hard, you have to look at the three distinct layers where modern streaming pipelines manipulate vocal performance without your awareness.
For the Narrative Purist: The Algorithmic Snip
This is where predictive software flags natural physical pauses as latency. If an actor takes a long, agonizing drag from a prop cigar before murmuring an answer, the algorithm interprets the pause as an anomalous audio drop-out. The software automatically applies a micro-crossfade, tightening the gap by 200 to 400 milliseconds. You sense the dialogue moving too fast, even though the video frames remain technically unaltered.
For the Global Subscriber: The Dub-Match Drift
When high-budget productions release simultaneously across dozens of countries, localizing languages like German or Japanese often requires longer phonetic runs than conversational English. Rather than letting the subtitle track breathe, automated conform engines stretch or compress the original actor’s spoken pace to ensure visual parity with overseas voice actors. The vocal track becomes elastic, stretched out or jammed together to satisfy a standardized digital layout.
For the Home Theater Enthusiast: The Loudness Harmonizer
Modern streaming apps apply aggressive dynamic range compression directly within the television hardware. When whispered subtext is digitally forced to match the decibel level of an explosive crash, the delicate pitch shifts in an actor’s throat disappear entirely. Oldman’s legendary vocal subtleties are flattened into a single, uniform acoustic plane designed to play cleanly through tinny television speakers.
Reclaiming the Room: How to Tune Your Soundstage
You do not have to accept an automated audio feed that mangles dramatic delivery. By disabling factory default settings on your playback devices, you can restore much of the natural timing intended by the director and cast.
- Disable all automated speech enhancement filters on your smart TV or soundbar, as these processing modes actively clip trailing vowels and breathing pauses.
- Switch your streaming application’s audio output from secondary mixed tracks to the original English uncompressed 5.1 or Dolby Atmos core stream.
- Turn off automatic volume leveling or night mode, which compress the dynamic crests and troughs where dramatic pauses live.
- Select direct audio passthrough within your receiver menus, forcing your sound hardware to play the audio stream exactly as delivered without algorithmic EQ resyncing.
The Human Pause as an Act of Resistance
When an artist of Gary Oldman’s caliber draws a line in the sand over a few missing frames of breath, he is defending the last analog frontier of cinematic storytelling. In a media landscape driven by instant stimulation and hyper-optimized content delivery, silence is the only tool that demands patience from an audience. It forces you to sit with discomfort, to register grief, to anticipate danger.
When software strips that silence away, entertainment becomes pure transactional noise. Caring about vocal timing is not about being precious over technical mechanics; it is about protecting the fragile space where human vulnerability lives. The next time you watch a scene where the silence feels heavy enough to drown in, savor every quiet millisecond. It was fought for on the soundstage, defended against an algorithm, and kept alive just for your ears.
“Acting does not live merely in the words you push out into the light, but in the terrifying length of time you dare to hold the dark before you speak them.”
| Key Point | Detail | Added Value for the Reader |
|---|---|---|
| Algorithmic Cadence Resync | Cloud-based localization software adjusts English vocal gaps to align with international dubbing parameters. | Explains why streaming dialogue occasionally feels rushed or disconnected from facial expressions. |
| Dynamic Compression Clipping | Automated processing treats long character hesitations as accidental audio dropout or unnecessary latency. | Reveals why complex dramatic scenes lose their tension on factory-calibrated consumer hardware. |
| Acoustic Reclamation | Disabling built-in TV audio dialogue enhancers preserves original soundstage master pacing. | Provides practical setup adjustments to recover theatrical audio fidelity in your living room. |
Frequently Asked Questions
Did the studio intentionally alter Gary Oldman’s voice?
The studio did not rewrite his lines, but their automated localization pipeline applied predictive algorithms that altered the timing between his sentences without his knowledge or creative consent.Why do streaming platforms use automated cadence tools?
These tools speed up the localization workflow, allowing multi-language subtitles and foreign dubs to launch globally on the exact same date without manual re-editing from sound mixers.Can you actually notice a change of only a few milliseconds?
Yes. Human speech patterns rely on precise temporal cues; when an anticipated dramatic pause is shortened by even a fraction of a second, the brain detects an unnatural cadence.Does this algorithmic alteration affect the video footage?
Typically, the video stays identical while micro-edits and crossfades are applied strictly to the vocal track, creating a subtle, jarring disconnect between lip movement and audible breath.How can I hear the performance as it was originally recorded?
Opt for the uncompressed original audio stream, disable TV-side speech clarity enhancers, and whenever possible, view theatrical physical media releases that bypass cloud-based audio updates.